MiniCPM5-1B-Agentic-Tooluse-v3 is a 1B-parameter open-weight function-calling model fine-tuned from MiniCPM5-1B. Quantized to GGUF, it runs entirely offline on a CPU — no GPU, no cloud API, no data leaving your machine — and works out of the box with llama.cpp, Ollama, LM Studio, koboldcpp and text-generation-webui.
The model is trained to parse a tool schema plus a natural-language request and emit a structured, correctly-named, correctly-valued function call — the core skill behind LangChain agents, LlamaIndex pipelines, AutoGen, CrewAI, MCP tool servers, ReAct loops and home-automation assistants. On a held-out 300-example benchmark it reaches 74.67% exact-argument accuracy.
Training
Unlike most small open tool-calling models that stop at supervised fine-tuning, this one goes through a two-stage pipeline:
- QLoRA supervised fine-tuning (SFT) on tool-calling trajectories from ToolACE.
- GRPO reinforcement learning on top of the SFT checkpoint, specifically rewarding the two hardest parts of tool calling: choosing the right function name and getting every argument value exactly right.
Compared with GPT-4o / Claude function calling, the author notes the model trades some absolute accuracy for being free, local, private, zero cost per call, and fine-tunable.
Results
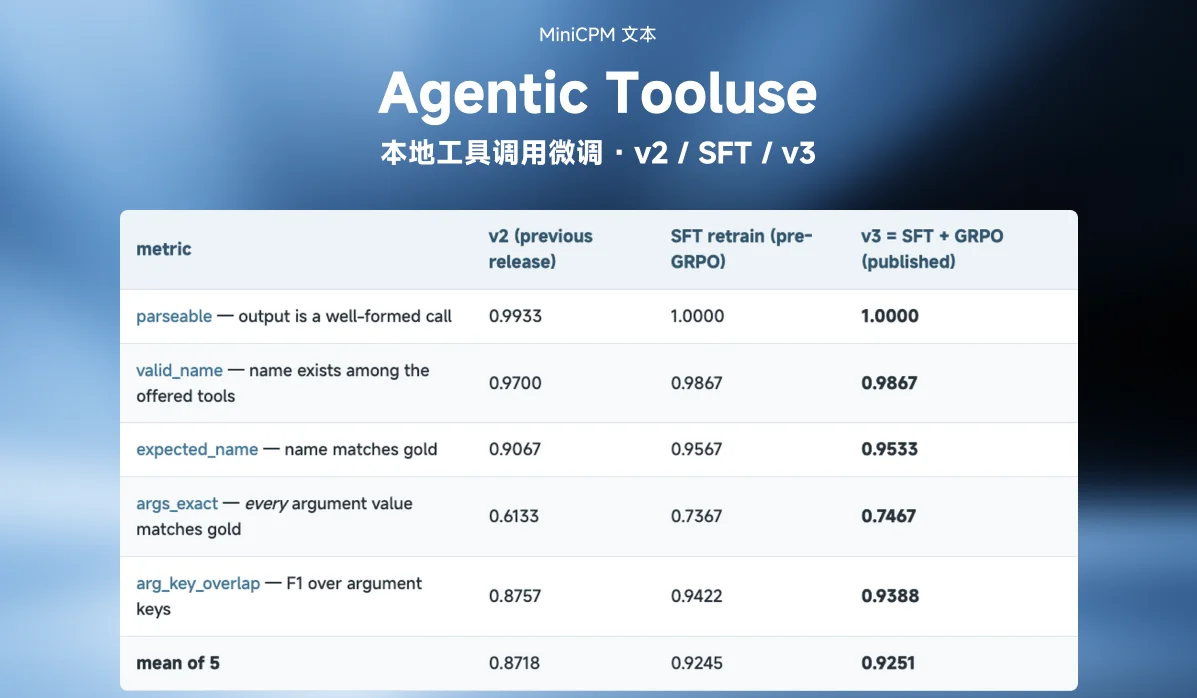
Evaluated on a held-out 300-example slice drawn from a seeded shuffle of ToolACE. The base-model column is the same model with the same prompt and no adapter. The published weights are SFT + GRPO; the SFT column is kept because every negative result below is measured against it.
| Metric | v2 (previous release) | SFT retrain (pre-GRPO) | v3 = SFT + GRPO (published) |
|---|---|---|---|
parseable — output is a well-formed call | 0.9933 | 1.0000 | 1.0000 |
valid_name — name exists among the offered tools | 0.9700 | 0.9867 | 0.9867 |
expected_name — name matches gold | 0.9067 | 0.9567 | 0.9533 |
args_exact — every argument value matches gold | 0.6133 | 0.7367 | 0.7467 |
arg_key_overlap — F1 over argument keys | 0.8757 | 0.9422 | 0.9388 |
| Mean of 5 | 0.8718 | 0.9245 | 0.9251 |
GRPO buys +0.0100 on args_exact, the metric that matters most here, and gives back 0.0034 (one test example each) on expected_name and arg_key_overlap. The author reports this trade rather than hiding it: the mean moves only +0.0006, so this is a targeted gain on the hardest metric, not a broad improvement.
Full 8-Metric Benchmark (held-out test set, n=300)
Mirroring the v2 evaluation format, with Base, v2 and v3 side by side on a single consistent harness and test slice:
| Metric | Base MiniCPM5-1B | v2 (previous release) | v3 (this model) | Delta (v2 → v3) |
|---|---|---|---|---|
| parseable_rate | 0.0133 | 0.9933 | 1.0000 | +0.0067 |
| valid_name_rate | 0.0133 | 0.9700 | 0.9867 | +0.0167 |
| expected_name_rate | 0.0133 | 0.9267 | 0.9533 | +0.0267 |
| args_exact_rate | 0.1500 | 0.6533 | 0.7467 | +0.0934 |
| arg_key_overlap | 0.0033 | 0.7517 | 0.9388 | +0.1871 |
| no_schema_copy_rate | 1.0000 | 1.0000 | 0.9967 | -0.0033 |
| no_repetition_rate | 0.9967 | 1.0000 | 0.3400 | -0.6600 |
| stopped_cleanly_rate | 0.0000 | 0.1500 | 0.0000 | -0.1500 |
Note: the v2 values for expected_name, args_exact and arg_key_overlap differ between the two tables in the model card; they are reproduced here as published.
What the additional metrics mean:
no_schema_copy_rate— the model did not copy the tool schema's own field description verbatim into an argument value.no_repetition_rate— the completion contained no duplicated function-call block or degenerate repeated-phrase loop. This is a known weakness: the model often keeps generating filler content after the tool call completes.stopped_cleanly_rate— the model stopped naturally right after the completed</function>tag with no trailing tokens.
So in practice, use a parser that treats the first completed <function>...</function> block as the action boundary — do not rely on natural end-of-generation.
Available Quantizations
| File | Quant | Size | Best for |
|---|---|---|---|
MiniCPM5-1B-Agentic-Tooluse-v3.F16.gguf | F16 | ~2.02 GB | Maximum quality, GPU or high-RAM CPU inference |
MiniCPM5-1B-Agentic-Tooluse-v3.Q8_0.gguf | Q8_0 | ~1.07 GB | Near-lossless, recommended default for most users |
MiniCPM5-1B-Agentic-Tooluse-v3.Q4_K_M.gguf | Q4_K_M | ~656 MB | Smallest and fastest — edge devices, phones, CPU-only/low-RAM machines |
All three run well on CPU; a GPU just makes them faster.
Quick Start
llama.cpp:
./llama-cli -m MiniCPM5-1B-Agentic-Tooluse-v3.Q8_0.gguf -p "Your prompt with tool schema here"
llama-server (OpenAI-compatible API, works with most agent frameworks):
./llama-server -m MiniCPM5-1B-Agentic-Tooluse-v3.Q4_K_M.gguf --port 8080
Ollama:
# Create a Modelfile containing:
#   FROM ./MiniCPM5-1B-Agentic-Tooluse-v3.Q8_0.gguf
ollama create minicpm5-tooluse-v3 -f Modelfile
ollama run minicpm5-tooluse-v3
LM Studio: download one of the .gguf files above directly through the LM Studio search/download UI.
Turn Thinking Off
MiniCPM5-1B ships with a built-in <think>...</think> chat template. Always use enable_thinking=False for tool calling — with thinking on, the model spends its token budget on reasoning and may never reach a completed function call. All benchmark numbers on this page use thinking off.
prompt = tokenizer.apply_chat_template(
    messages, tools=tools, add_generation_prompt=True,
    enable_thinking=False,
    tokenize=False,
)
Use Cases
- Fully local / offline / private AI agents
- Home automation and smart-home voice assistants
- Mobile, browser-extension and embedded/IoT tool-calling agents
- Cost-sensitive, high-volume backends that can't afford large-model API costs per call
- A function-calling backbone for LangChain, LlamaIndex, AutoGen, CrewAI and MCP-based agent stacks
- Hobbyist and research experiments with small-model agentic reasoning
Related Repos
| Format | Repository |
|---|---|
| v3 LoRA adapter (PEFT, smallest download, fine-tune further) | MiniCPM5-1B-Agentic-Tooluse-QLoRA-v3 |
| v3 merged full-weight FP16 (transformers / vLLM / SGLang) | MiniCPM5-1B-Agentic-Tooluse-v3-Merged-FP16 |
| v3 GGUF quantizations (llama.cpp / Ollama / LM Studio) | MiniCPM5-1B-Agentic-Tooluse-v3-GGUF |
| v2 LoRA adapter | MiniCPM5-1B-Agentic-Tooluse-QLoRA-v2 |
| v2 merged FP16 | MiniCPM5-1B-Agentic-Tooluse-Merged-FP16 |
| v2 GGUF | MiniCPM5-1B-Agentic-Tooluse-GGUF |
Links
- Hugging Face: MiniCPM5-1B-Agentic-Tooluse-v3-GGUF
- Base model: openbmb/MiniCPM5-1B
- Training data: Team-ACE/ToolACE