tiny-llm is a minimal LLM inference engine for MiniCPM5-1B, built purely in Rust. The author built it to study the fundamentals of large language models — every understanding is expressed directly in the code, in the hope that it helps others learn too. It is also groundwork for bringing AI algorithms into the author's note app OpenNote. The project was inspired by tiny-vllm.
Key features
- CPU-only inference: no GPU required.
- Minimal KV cache: a simple KV cache that boosts performance by up to 6x.
- Hand-written algorithms and tensor operations: all algorithms and tensor ops are written by hand; the author learned a lot from
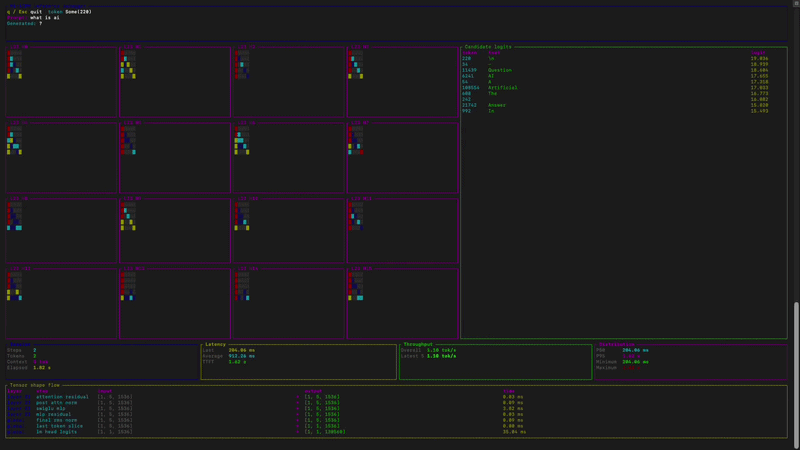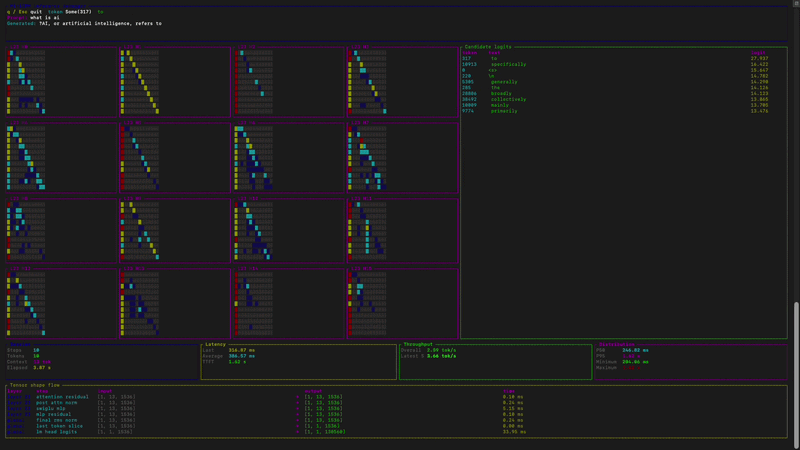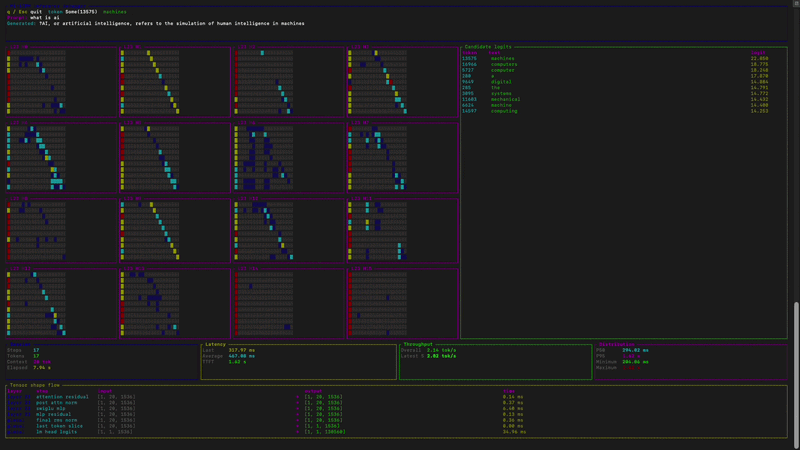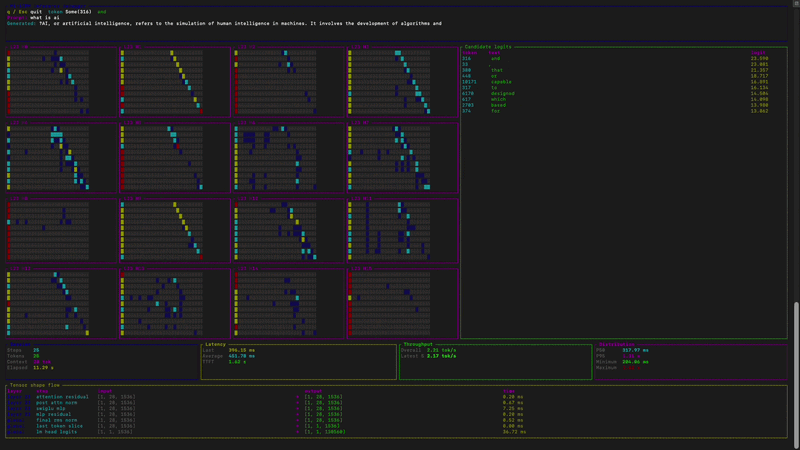
candle's tensor implementation. - TUI visualization: a real-time view of how the model "thinks", including attention heatmaps and candidate logits.
What's implemented
| Component | Details |
|---|---|
| Embedding | Token ID lookup via embedding table |
| RoPE | Rotary position embeddings |
| Attention | Multi-head attention with GQA (Grouped Query Attention) |
| MLP | SwiGLU activation function |
| Normalization | RMSNorm |
| Residual connections | Standard skip connections after attention and MLP |
The hand-written TinyTensor currently performs on par with or slightly faster than candle. The main branch holds the hand-written version, candle-based-implementation holds a candle-based version, and without-kv-cache holds the version without a KV cache. The repository also documents completed and attempted optimizations in OPTIMIZATIONS.md and explains how to read the TUI in TUI.md.
Code walkthrough
LLM
src/tensors.rs: the hand-writtenTinyTensortype and basic tensor operations.src/algorithms.rs: LLM operations such as RMSNorm, RoPE, attention, and SwiGLU.src/main.rs: model loading and thepredict_next_token_with_kv_cacheinference flow.src/simd.rs: SIMD optimizations for tensor operations.src/kv_cache.rs: the KV cache for this minimal engine.src/inference.rs: the main inference logic.
TUI
src/tui.rs: the terminal UI, attention heatmaps, and candidate logits.src/benchmark.rs: live latency, throughput, and per-operation timing statistics.
Quick start
- Download MiniCPM5-1B from Hugging Face into a directory such as
./models/minicpm5-1b/; it should containconfig.json,model-00000-of-00001.safetensors, andtokenizer.json. - Build and run:
cargo run --release -- ./models/minicpm5-1b "What is artificial intelligence?"
Press q to quit early.
Links
- GitHub: AspadaX/tiny-llm