MiniCPM-o 4.5
MiniCPM-o Omnimodal Series
Start from an audio clip or a single image to get your first omnimodal response: speech-to-text, text-to-speech, voice cloning, and omni recognition that feeds vision and speech together. Pick the example that matches your task and build your audio-video app from there.
| Example | Input → Output | Notes |
|---|---|---|
| Speech-to-Text | Audio → text | ASR / spoken QA, reads audio via librosa |
| Text-to-Speech | Text → audio | Requires model.init_tts(), writes a .wav |
| Voice cloning | Reference audio + text → audio | Clone a timbre from one reference clip |
| Omni recognition | Image + text → text | Object recognition and object spotting |
Models are loaded with AutoModel.from_pretrained(..., trust_remote_code=True). Use sdpa or flash_attention_2 for the attention implementation — do not use eager.
Speech-to-Text
Initialize model
Python
import torch
import librosa
from transformers import AutoModel, AutoTokenizer

model_path = 'openbmb/MiniCPM-o-2_6'
model = AutoModel.from_pretrained(model_path, trust_remote_code=True,
                                  # sdpa or flash_attention_2, no eager
                                  attn_implementation='sdpa', torch_dtype=torch.bfloat16)
model = model.eval().cuda()
tokenizer = AutoTokenizer.from_pretrained(model_path, trust_remote_code=True)

model.init_tts()
model.tts.float()
Usage example
Python
audio_input, _ = librosa.load('./assets/recongize.wav', sr=16000, mono=True)
msgs = [{'role': 'user', 'content': [audio_input]}]
res = model.chat(
    msgs=msgs,
    image=None,
    tokenizer=tokenizer,
    sampling=True,
    max_new_tokens=4096,
    use_tts_template=True,
    temperature=0.3,
    generate_audio=True,
)

print("asr result:", res)
Example Output
Plain Text
asr result: 你好!我是MiniCPM 3 Omni,由面壁智能科技有限责任公司研发。我今天能为你提供什么帮助?
Text-to-Speech
Initialize model
Python
import torch
import librosa
from transformers import AutoModel, AutoTokenizer

model_path = 'openbmb/MiniCPM-o-2_6'
model = AutoModel.from_pretrained(model_path, trust_remote_code=True,
                                  # sdpa or flash_attention_2, no eager
                                  attn_implementation='sdpa', torch_dtype=torch.bfloat16)
model = model.eval().cuda()
tokenizer = AutoTokenizer.from_pretrained(model_path, trust_remote_code=True)

model.init_tts()
model.tts.float()
Usage example
Python
text_to_speak = """
男声以较低的音高,较低的音量,充满喜悦并感到深刻的幸福,表现得非常亲切与满足,“I have a dream, 世界会更好。”
"""

ref_audio_path = './assets/male_example.wav'
ref_audio, _ = librosa.load(ref_audio_path, sr=16000, mono=True)

msgs = [{'role': 'user', 'content': [text_to_speak, ref_audio]}]

tts_result = model.chat(
    msgs=msgs,
    image=None,
    tokenizer=tokenizer,
    sampling=True,
    temperature=0.3,
    max_new_tokens=4096,
    use_tts_template=True,
    generate_audio=True,
    output_audio_path='text2speech_output.wav',
    ref_audio=ref_audio
)
Voice cloning
Initialize model
Python
import torch
import librosa
from transformers import AutoModel, AutoTokenizer

model_path = 'openbmb/MiniCPM-o-2_6'
model = AutoModel.from_pretrained(model_path, trust_remote_code=True,
                                  # sdpa or flash_attention_2, no eager
                                  attn_implementation='sdpa', torch_dtype=torch.bfloat16)
model = model.eval().cuda()
tokenizer = AutoTokenizer.from_pretrained(model_path, trust_remote_code=True)

model.init_tts()
model.tts.float()
Usage example
Python
prompt = "Please repeat the user's speech, including voice style and speech content."
audio_input, _ = librosa.load('./assets/male_example.wav', sr=16000, mono=True)
msgs = [{'role': 'user', 'content': [prompt, audio_input]}]
res = model.chat(
    msgs=msgs,
    image=None,
    tokenizer=tokenizer,
    sampling=True,
    max_new_tokens=4096,
    use_tts_template=True,
    temperature=0.3,
    generate_audio=True,
    output_audio_path='./voice_clone_output.wav',
)
Omni recognition
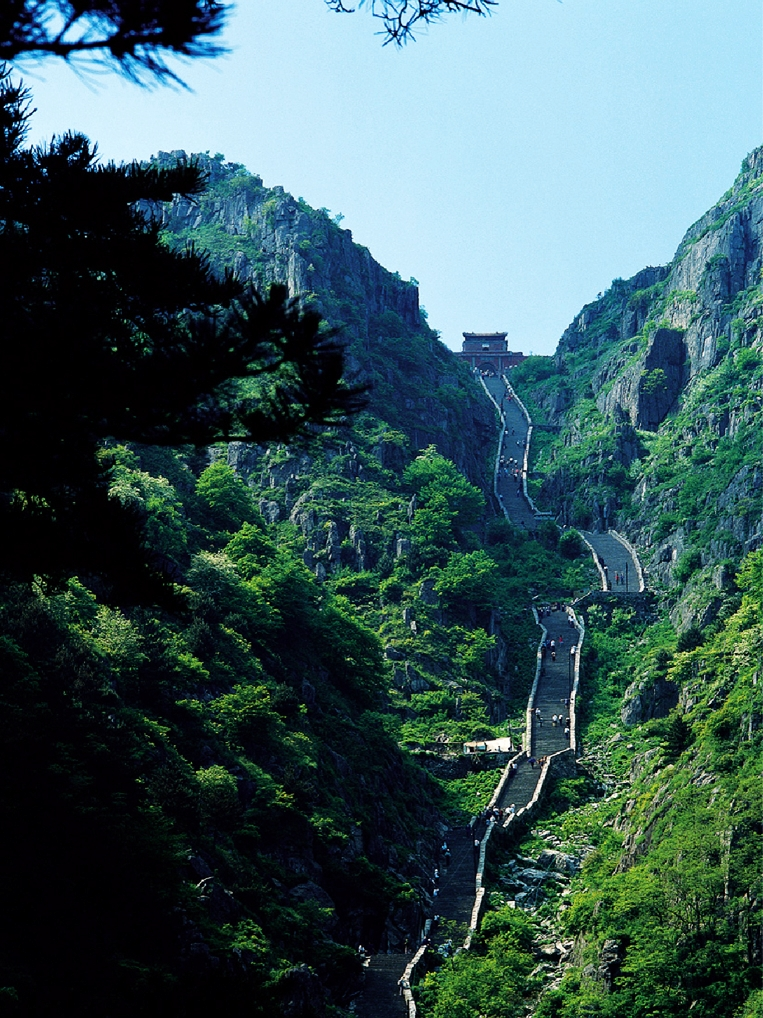
We can use MiniCPM-V-4_5 to perform object recognition tasks on images.
Python
from PIL import Image
import torch
from transformers import AutoModel, AutoTokenizer

model_path = 'openbmb/MiniCPM-V-4_5'
model = AutoModel.from_pretrained(model_path, trust_remote_code=True,
                                  # sdpa or flash_attention_2, no eager
                                  attn_implementation='sdpa', torch_dtype=torch.bfloat16)
model = model.eval().cuda()
tokenizer = AutoTokenizer.from_pretrained(
    model_path, trust_remote_code=True)

image = Image.open('./assets/single.png').convert('RGB')

question = "What is the landform in the picture?"
msgs = [{'role': 'user', 'content': [image, question]}]

answer = model.chat(
    msgs=msgs,
    image=image,
    tokenizer=tokenizer
)
print(answer)
Image:
Result:
Plain Text
The landform in the picture is a mountain range. The image shows steep cliffs, rugged terrain, and a winding path that ascends between two prominent rocky peaks covered with green vegetation. This type of landscape features high elevations and dramatic slopes characteristic of mountains.
Object Spot
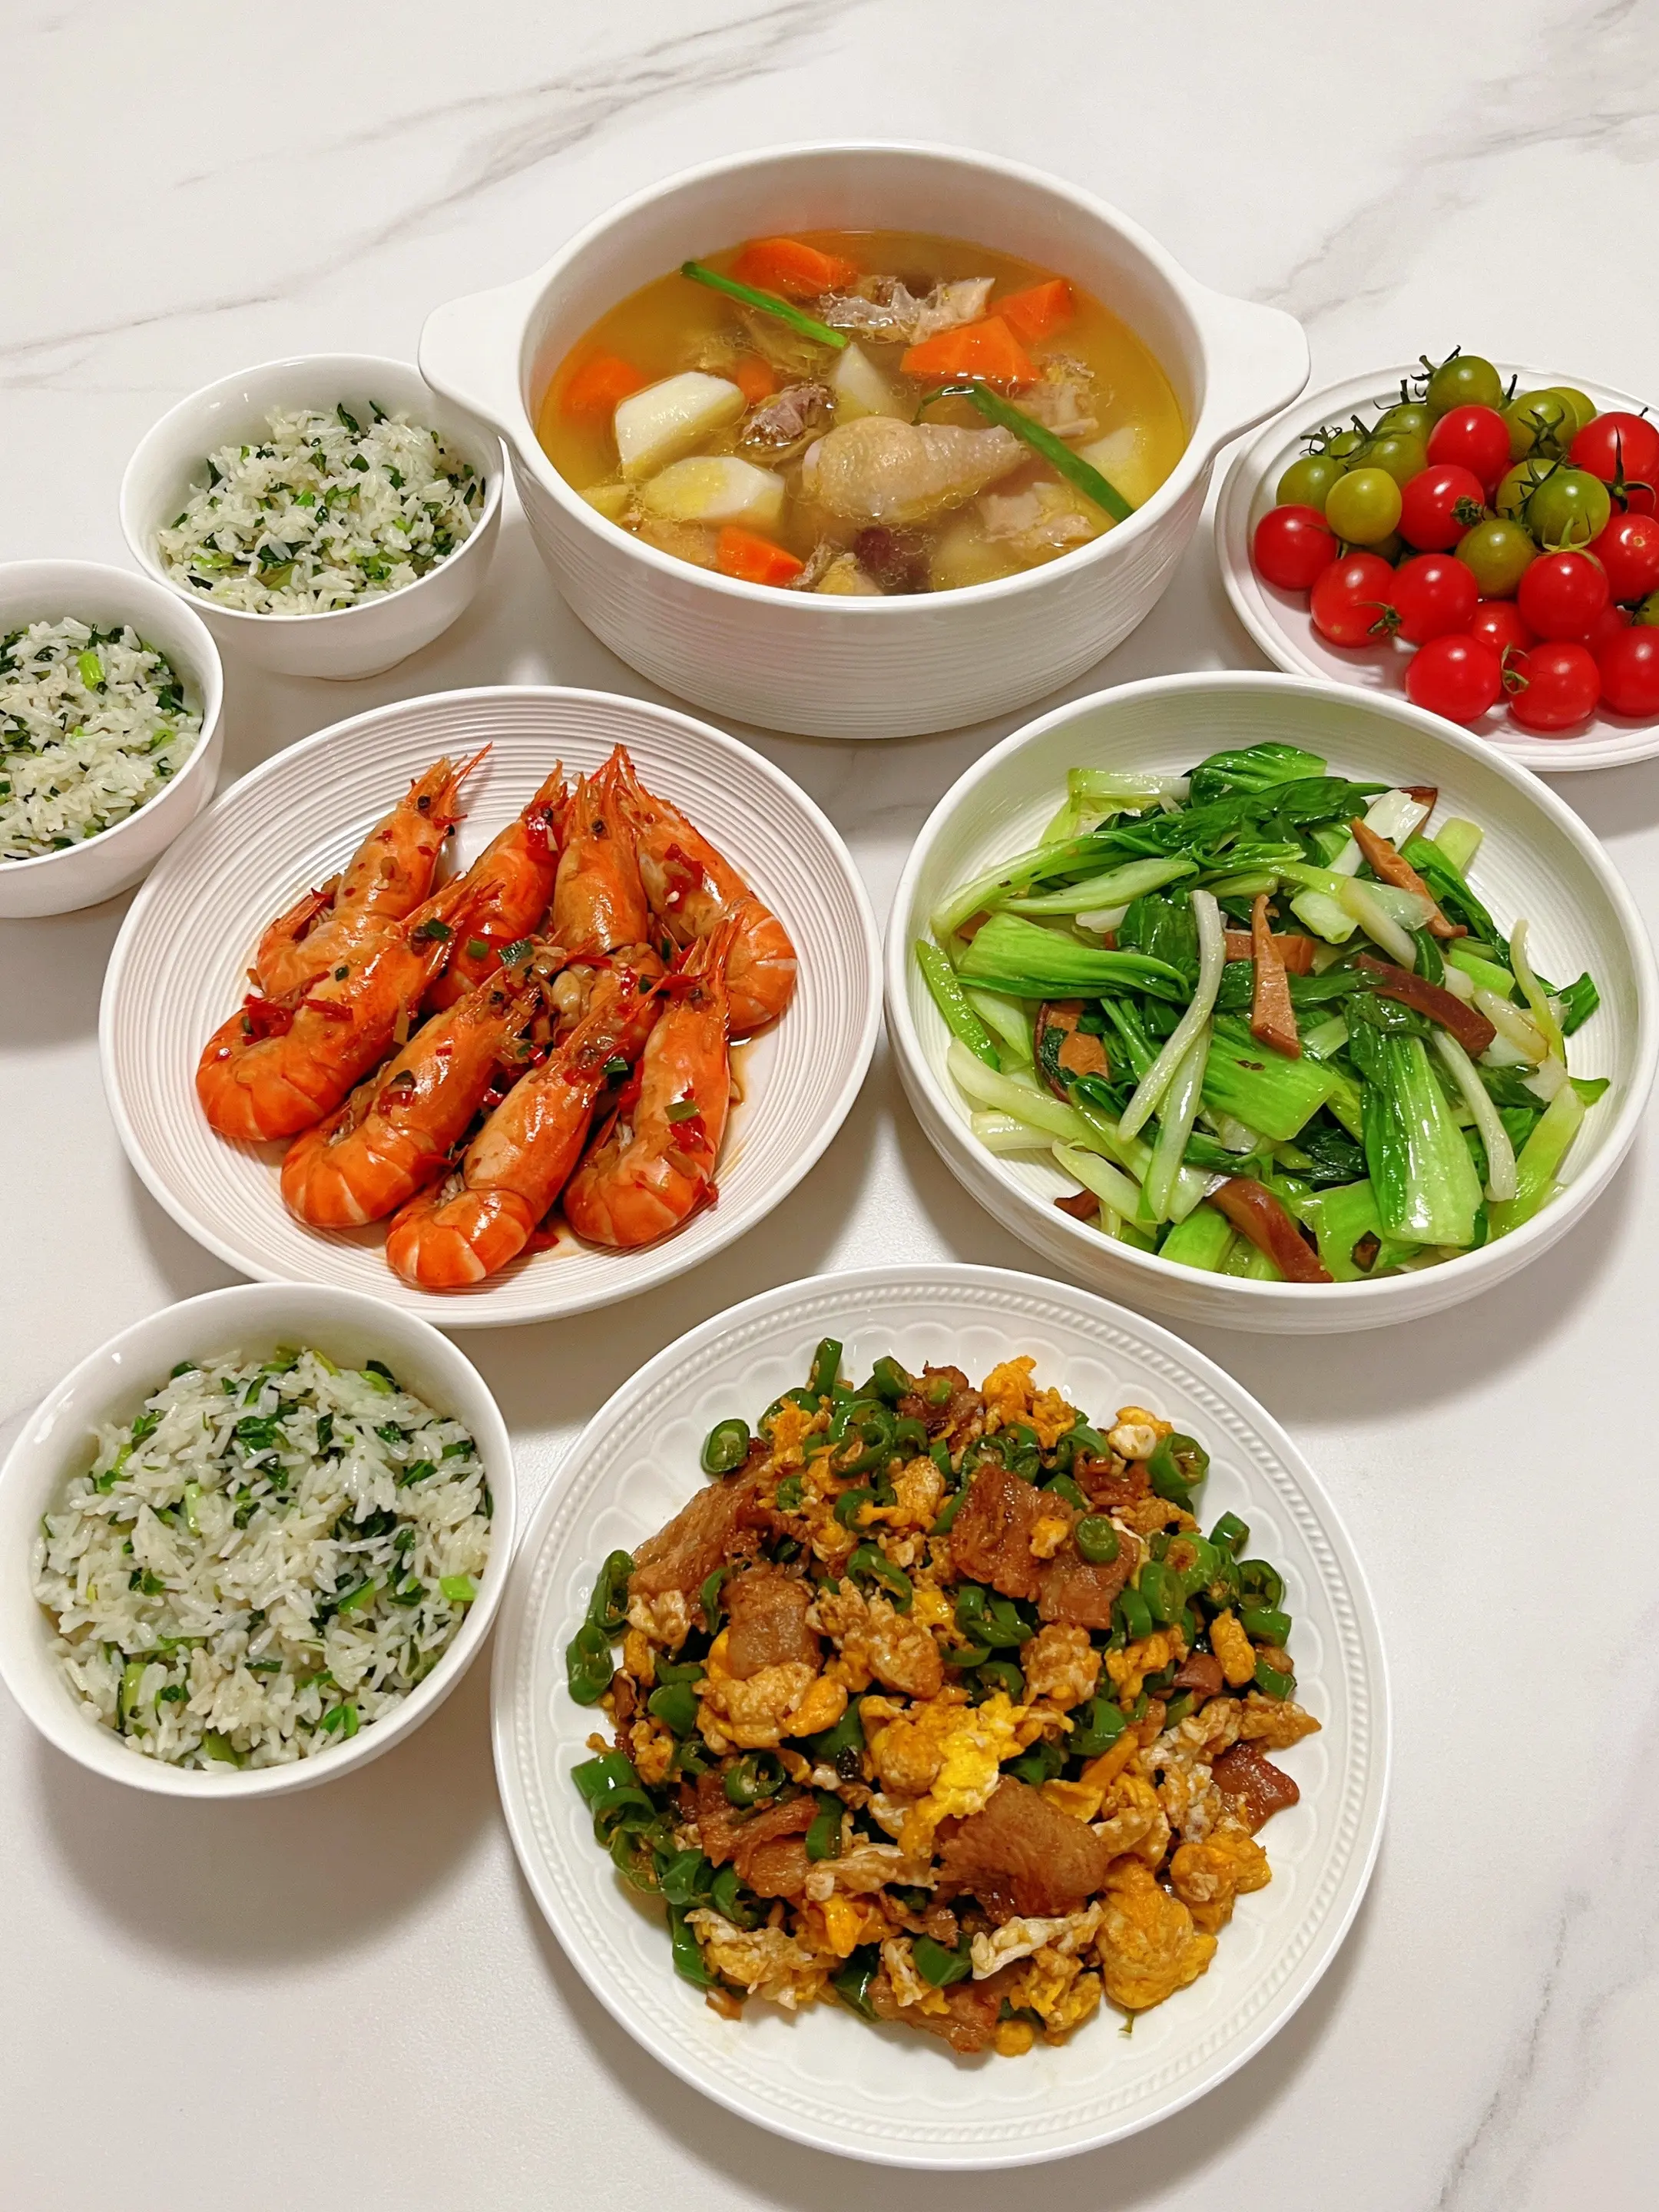
We can also use MiniCPM-V-4_5 to perform object spotting tasks on images.
Python
from PIL import Image
import torch
from transformers import AutoModel, AutoTokenizer

model_path = 'openbmb/MiniCPM-V-4_5'
model = AutoModel.from_pretrained(model_path, trust_remote_code=True,
                                  # sdpa or flash_attention_2, no eager
                                  attn_implementation='sdpa', torch_dtype=torch.bfloat16)
model = model.eval().cuda()
tokenizer = AutoTokenizer.from_pretrained(
    model_path, trust_remote_code=True)

image = Image.open('./assets/multi_object.png').convert('RGB')

question = "Identify food in the image and return their bounding box and Chinese and English name in JSON format."
msgs = [{'role': 'user', 'content': [image, question]}]

answer = model.chat(
    msgs=msgs,
    image=image,
    tokenizer=tokenizer
)
print(answer)
Image:
Result:
JSON
{
  "food_1": {
    "bounding_box": "<box>520 637 644 782</box>",
    "chinese_name": "炒鸡蛋",
    "english_name": "Fried eggs"
  },
  "food_2": {
    "bounding_box": "<box>9 329 194 480</box>",
    "chinese_name": "蔬菜白米饭",
    "english_name": "Vegetable white rice"
  },
  "food_3": {
    "bounding_box": "<box>43 505 310 670</box>",
    "chinese_name": "蔬菜白米饭",
    "english_name": "Vegetable white rice"
  },
  "food_4": {
    "bounding_box": "<box>15 157 312 327</box>",
    "chinese_name": "蔬菜白米饭",
    "english_name": "Vegetable white rice"
  },
  "food_5": {
    "bounding_box": "<box>435 20 737 324</box>",
    "chinese_name": "鸡汤",
    "english_name": "Chicken soup"
  },
  "food_6": {
    "bounding_box": "<box>496 341 951 574</box>",
    "chinese_name": "炒青菜",
    "english_name": "Stir-fried greens"
  },
  "food_7": {
    "bounding_box": "<box>203 345 542 574</box>",
    "chinese_name": "蒜蓉粉丝蒸虾",
    "english_name": "Garlic and vermicelli steamed shrimp"
  },
  "food_8": {
    "bounding_box": "<box>729 1 1000 314</box>",
    "chinese_name": "圣女果",
    "english_name": "Cherry tomatoes"
  }
}